In a world where threat actors can leverage AI technologies to discover and exploit vulnerabilities in just minutes, defenders must also take advantage of AI to bolster their capacity for finding and mitigating risks through practices like AI pentesting. Recognizing this need, a growing number of vendors now offer AI penetration testing platforms to supplement traditional penetration testing. But with multiple options available, which AI-powered pentesting products are the best fit for a given use case?
To provide guidance, we compare and contrast seven leading AI pentesting platforms: CyCognito, Horizon3.ai, Pentera, XBOW, Aikido Security, Cobalt, and Synack. While all of these vendors provide core AI pentesting capabilities, they differ significantly in their approaches.
These differences come down to use case, the systems being tested, and how often testing runs. Some vendors test a defined set of applications in greater depth than a manual engagement allows. Others operate from inside the network, validate existing security controls, or pair automation with human testers. Others still test the organization’s entire external footprint, including assets that were never added to a scope.
In this article, we explore these different approaches and the considerations that should guide the choice between them.
Considerations for choosing an AI penetration testing tool
The considerations that go into choosing an AI penetration testing platform fall into two groups. Some are shared across vendors and apply to any security tool. They belong in every evaluation, but they rarely separate one AI pentesting vendor from another:
- Compliance: Whether the platform and its outputs satisfy the frameworks the organization is subject to, and whether its processes align with regulatory requirements and internal security practices.
- Safety of the testing process: How the platform avoids disrupting production systems and how scope is enforced. This also maps to maturity and the track record of the product and the company.
- Testing methodology: Whether the platform can chain individual weaknesses into full attack paths, perform business logic testing (rather than only known vulnerabilities), and simulate real attacker behavior.
- Integration: How findings flow into ticketing, remediation, and reporting workflows.
Other considerations differ sharply from vendor to vendor, and they are the ones that determine which use case a platform fits best:
- Scoping method: Platforms differ in how the set of test targets is defined. Some AI pen testing tools work off a list of applications or ranges supplied by the customer, some test whatever is reachable from the point where they are deployed, and some build the scope themselves from what the organization exposes.
- Scope per run: The number of targets a single run can cover varies from a few applications to the organization’s entire inventory. Per-engagement and per-target models tend to cap this number.
- Cadence: Security testing may run on demand, per engagement, on a schedule, or continuously. The right cadence depends on how quickly the environment changes.
- Reach: No vendor covers every environment equally. Some concentrate on internal networks and Active Directory, others on web applications and APIs, and others on the external footprint across web, API, cloud, and AI tools.
- Human attestation: Some platforms are human-led or human-validated. Manual testing comes with its own set of downsides in cost and speed, but it can also produce a signed report for auditors, which automated platforms generally cannot. This makes human-led platforms a good fit for auditing use cases.
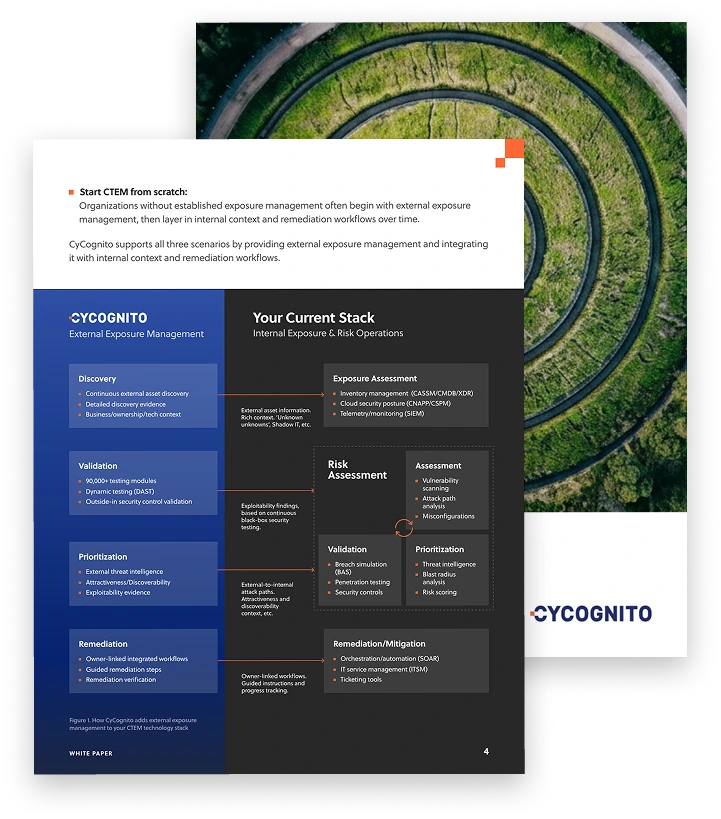
Operationalizing CTEM Through External Exposure Management
CTEM breaks when it turns into vulnerability chasing. Too many issues, weak proof, and constant escalation…
This whitepaper offers a practical starting point for operationalizing CTEM, covering what to measure, where to start, and what “good” looks like across the core steps.
Best AI pentesting vendors, compared
The table below summarizes how the seven vendors compare on these considerations, and the use case each is best suited for.
| Vendor | Scoping method | Scope (targets per run) | Cadence | Reach | Human attestation | Best for |
|---|---|---|---|---|---|---|
| CyCognito | Automated test plans built from exposure context | Hundreds to thousands | Continuous | External, web apps, APIs, cloud, AI services | No | Testing beyond the priority asset list |
| Horizon3.ai | Network segment or range selected at deployment | Hundreds to thousands | Scheduled runs | Internal, Active Directory, cloud, external | No | Internal network testing |
| Pentera | Customer-defined environment | Hundreds to thousands | Scheduled runs | Security controls, internal, external, cloud | No | Security control validation |
| XBOW | Customer-supplied applications | Tens to hundreds | On demand | External, web apps, APIs | No | Deep testing of priority applications |
| Aikido Security | Connected repositories and applications | Tens to hundreds | Per pipeline run | Web apps, APIs | No | Developer-run testing before release |
| Cobalt | Engagement scope agreed with testers | A few | Per engagement | External, web apps, APIs, AI services | Yes | Audit-ready pentest reports |
| Synack | Engagement scope agreed with testers | Tens | Per engagement | External, web apps, APIs, AI services | Yes | Human-validated continuous testing |
Now, let’s take a detailed look at seven widely used AI penetration testing solutions.
CyCognito
Description
CyCognito is a continuous AI-powered penetration testing platform that tests the whole external attack surface. It discovers everything an organization exposes, including the subsidiaries, forgotten systems, and shadow assets that rarely make it onto a pentest scope, and builds each test plan from the context it already holds on every asset. It decides what to test across the full surface, including the assets an organization does not know it has.
That context is what makes the testing economical, and it comes from the layer underneath: CyCognito’s industry-leading attack surface management (ASM) platform, which discovers every internet-facing asset and runs more than 100,000 deterministic checks against it continuously.
Because the mapping and the known checks are already done, the agent does no reconnaissance from scratch and goes straight to exploitation. The same foundation drives CyCognito’s Target Graph™, the orchestration layer that decides which assets to test, how deep to go, and which techniques to apply.
Focus
CyCognito focuses on the exposures that scoped testing reaches least: web applications, APIs, cloud services, and AI systems. It tests each for authentication and authorization bypass, business logic flaws, exposed data, and the prompt-injection and agent-access weaknesses that AI-coupled assets introduce. Its AI agents orchestrate the same penetration testing tools a human tester would reach for, so web application testing goes past signature matching to the multi-step flaws scanners miss.
Approach
The approach starts with reconnaissance: CyCognito maps every asset an organization exposes and attributes it to the business unit or subsidiary that owns it. Deterministic testing then runs continuously across that full inventory, flagging known vulnerabilities, misconfigurations, and exposed data.
Both feed the Target Graph™, which estimates the risk each asset carries by weighing threat, attractiveness to attackers, exploitability, and business importance, and turns that estimate into continuous AI pentesting missions. AI agents run those missions and prove what is exploitable, handing over a working exploit path for each finding. Nothing reaches the report that was not demonstrated, which keeps false positives low.
Best for
CyCognito is a strong choice when the priority is continuous testing of a large, constantly changing external attack surface, rather than performing conventional point-in-time pentests on a small number of explicitly scoped applications. It is particularly well suited to large enterprises with extensive web, API, cloud, and AI exposure, organizations worried about unknown internet-facing assets, and teams that want automated validation to operate continuously rather than waiting for an annual pentest.
Horizon3.ai (NodeZero)
Description
Horizon3.ai’s NodeZero is one of the most widely adopted autonomous pentesting platforms and a leader in testing internal networks. Its strength is depth inside the network: placed within a segment, it shows how far an attacker who has gained a foothold could get. Beyond the internal network, it tests the external ranges a customer specifies, cloud and Kubernetes environments from the inside, and web applications.
NodeZero is used by government agencies and large enterprises, and Horizon3 has published benchmark results showing it completing a standard Active Directory attack lab in a fraction of the time an expert tester needs.
Focus
NodeZero focuses on what an attacker can do once inside: harvesting credentials, moving laterally, escalating privileges, and abusing Active Directory until it reaches impact such as domain compromise or access to sensitive data. It tests for the weaknesses that make that possible, including weak and reused credentials, exploitable vulnerabilities on internal hosts, misconfigured services, and permission flaws in Active Directory, cloud identities, and Kubernetes. It also measures whether endpoint, identity, and data security tools detect and stop those techniques.
Approach
NodeZero does not install agents on the systems it tests. For internal testing, a lightweight host is placed inside the network segment being tested. External tests run from Horizon3’s cloud against the ranges the customer supplies. Tests can run without credentials or with credentials the customer provides to reach further, on a schedule or on demand, and cover the hosts in the selected segment or range, typically hundreds to thousands. Each result is shown as the chain of steps that led to it, so teams can see which weakness to fix to break the path, and once it is fixed the same test can be re-run to confirm the path is closed.
Best for
NodeZero is a leading choice for organizations that want to know how far an attacker could get once inside their network. It is a strong fit for internal network and Active Directory testing, as well as cloud environments and the external ranges a team specifies, and it is especially valuable for teams that want frequent, repeatable internal testing between annual engagements.
Pentera

Description
Pentera describes itself as an AI-powered exposure validation platform, and its lead message is control-focused: safely test the defenses an organization already runs against real attacks, then prioritize the exposures those attacks prove. It covers internal networks, external assets, cloud, hybrid environments, web applications, and APIs. The platform combines deterministic attack logic with AI-driven adaptability.
Focus
Pentera focuses on proving how attacks progress and whether controls stop them. Internally, it executes full kill chains through lateral movement and privilege escalation. Externally, it tests how attackers could gain initial access, and in the cloud it tests against attacks on identities and hybrid environments. Targeted tests cover ransomware emulation, Active Directory password assessment, OWASP Top 10 categories, and known exploited vulnerabilities, and findings are prioritized by demonstrated impact rather than theoretical severity.
Approach
Tests run within a scope the customer defines, either starting with no credentials or starting from selected access to model a compromised account. Customer-controlled guardrails include attack throttling, impact limits, an emergency stop, and full audit logs. AI generates payloads that adapt to the application, identity, and data context a test encounters, and teams can explore validated attack paths in natural language. Remediation is orchestrated in the platform, and re-tests confirm when exposure has been reduced. A partnership with Recorded Future brings threat intelligence into testing. Each test covers the hosts in the defined environment, typically hundreds to thousands.
Best for
Pentera fits enterprise security validation programs that need evidence their defensive controls stop real attacks. It is used to validate firewalls, endpoint defenses, network segmentation, and other security controls, to test readiness for ransomware, and to demonstrate whether vulnerabilities form attack chains that lead to meaningful impact.
XBOW
Description
XBOW is an autonomous offensive security platform built around depth on web applications and APIs. Each application is supplied as a target by URL, and its AI agents explore it the way an attacker would, chain vulnerabilities into working attacks, and prove each one before it is reported. Teams can run many targets in parallel during an engagement, with the target list approved before testing starts.
XBOW has proven its approach on public bug bounty programs and industry benchmarks, and it presents findings as audit-ready: each comes with a working exploit, reproduction steps, impact, severity, and remediation guidance.
Focus
XBOW focuses on the vulnerabilities that live inside applications and APIs, including injection, cross-site scripting, server-side request forgery, broken access control, and exposed credentials, and on chaining them into attack paths that scanners and point-in-time pentests miss. It tests applications as they change and works with a web application firewall in place, identifying the firewall and attempting to bypass it as an attacker would.
Approach
Testing starts from a URL or an approved list of applications, within a scope the customer defines, and every agent action is logged and auditable. By default XBOW tests the way most attackers start, with no source code and no credentials. Credentials and additional context such as API specifications can be added for deeper, authenticated testing. Many agents work targets in parallel and on demand. Testing is non-destructive and pauses if a target becomes unstable, and XBOW retests once a fix is deployed. Only exploitable findings reach the report.
Best for
XBOW suits security teams that want their applications and APIs tested deeply and often, with proof behind every finding, especially organizations that release software frequently and want testing to keep pace. It is a strong fit for putting select critical applications through deep attacker-style testing.
Aikido Security

Description
Aikido Security is a developer-focused application security platform that covers code, cloud, and runtime in one system, and it includes AI pentesting as part of that platform. Its distinctive angle is its place in the CI/CD development workflow. Because Aikido already connects to an organization’s repositories, its pentesting agents can read the source code before they attack, mapping routes, permission models, and parameters, then test the running application with that understanding.
Aikido emphasizes speed and practicality for development teams: results come back quickly, fixes are opened as pull requests, and reports are produced for compliance frameworks such as SOC 2 and ISO 27001, for compliance and security professionals.
Focus
Aikido focuses on running applications and APIs, including REST, GraphQL, gRPC, and SOAP interfaces. It tests for injection flaws, access control issues such as IDOR and cross-user data leakage, authentication weaknesses, business logic errors, unsafe API behavior, and prompt injection in AI-powered features, with OWASP Top 10 coverage as a baseline.
Approach
Testing is white-box by default. The customer connects repositories and provides test credentials, and agents use the code to understand application logic, roles, and data flows before attacking the live target. Grey-box and black-box testing are also available.
The customer defines which domains can be attacked and which are only reachable. Separate agents re-exploit each finding to confirm it before it is reported, and fixes can be generated as pull requests and retested. In continuous mode, each push to staging triggers a scoped pentest of the changed code paths. An on-premises option runs the full stack on hardware inside the customer’s network.
Best for
Aikido suits development and AppSec teams that want penetration testing built into how they ship software, with fast results, automatic fixes, and retesting in the same workflow. It is a strong fit for organizations that need compliance-ready pentest reports for frameworks such as SOC 2 and ISO 27001, and for teams that want testing to keep pace with frequent releases, including those that need testing to stay entirely on their own premises.
Cobalt
Description
Cobalt’s core proposition is human expertise delivered through a platform. Engagements are run by the Cobalt Core, a vetted community of professional pentesters, with AI and automation handling the repetitive work around them. Cobalt offers human-led, AI-powered agentic pentesting alongside a fully autonomous option for faster, more frequent tests, keeping pentesters involved to review execution plans and enforce scope.
The platform is built around collaboration and compliance. Customers work directly with their testers, see findings as they arrive, and receive reports and letters of attestation suited to audit, regulatory, and customer requirements.
Focus
Cobalt focuses on professional offensive security across web applications, APIs, mobile apps on iOS and Android, cloud environments, internal and external networks, and AI models. Human testers concentrate on the work that rewards judgment, such as chained exploitation, business logic flaws, and complex adversarial scenarios, while AI takes on reconnaissance, scanning, and triage.
Approach
Customers define the scope, testing type, and cadence, and an engagement can move from scoping to active testing quickly. Pentesters from the Cobalt Core run the test while AI orchestration sequences and prioritizes tasks. Findings appear in the platform in real time, where customers can message testers directly. Integrations push findings into ticketing and remediation workflows, and fixes can be validated once they are deployed. The autonomous option runs faster, release-by-release tests under the same human oversight.
Best for
Cobalt suits organizations that want the depth and judgment of experienced human pentesters with the speed and convenience of a platform. It is a strong fit for compliance-driven programs that need audit-quality reports and attestation, for complex applications and business logic that reward human creativity, and for security teams that value working directly with the experts testing their systems.
Synack

Description
Similar to Cobalt, Synack combines AI pentesting tools with a vetted community of human security researchers, the Synack Red Team, under one platform. The model divides the work: AI explores broadly, and humans confirm what matters. An autonomous agent scopes targets, explores them, and attempts exploitation at scale. Synack Red Team researchers then validate every exploitable finding before it reaches the customer, and dig into the business logic and chained attack paths the AI cannot reach.
The approach is built to move organizations from point-in-time testing toward an ongoing validation program, and Synack works with government agencies and large enterprises that want human confirmation behind every result.
Focus
Synack focuses on web applications, APIs, cloud environments, hosts, and mobile apps, with dedicated testing for AI and LLM applications and an attack surface management capability alongside. Because human researchers review the results, it concentrates on findings where exploitability or business impact needs judgment, including business logic flaws and multi-step attack chains.
Approach
Customers scope an asset, launch a test, and review findings in the Synack platform. The AI agent handles discovery, triage, and initial exploitation, and Synack Red Team researchers validate each exploitable vulnerability and extend testing where human creativity is needed. The result is an AI-generated, human-validated report with findings, evidence, and remediation guidance, delivered through a platform that integrates with ticketing tools such as Jira. Tests run per engagement and can be repeated to build an ongoing validation program.
Best for
Synack suits enterprises and public-sector organizations that want frequent testing with a human expert confirming every finding. It is a strong fit for teams that need defensible evidence that an identified vulnerability is exploitable, for complex applications where business logic matters, and for programs moving from annual pentests toward ongoing validation.
Tips from the Expert
Dima Potekhin, CTO and Co-Founder of CyCognito, is an expert in mass-scale data analysis and security. He is an autodidact who has been coding since the age of nine and holds four patents that include processes for large content delivery networks (CDNs) and internet-scale infrastructure.
Most evaluations of penetration testing tools compare feature lists. The more useful test is how a vendor would handle your own environment. These are the questions worth asking before you commit.
- Count what is not on your list. Compare the number of internet-facing assets you own with the number that were pentested in the last year. The gap is where most exploitable exposure sits. Ask each vendor whether it tests that gap, and who decides what goes into scope: you, a deployment point, or the platform itself.
- Ask how the tool learns the target. An AI agent that starts with no knowledge of an asset spends much of its effort on reconnaissance before it can attack. A platform that already knows what each asset runs, who owns it, and what is already exposed can spend that effort on exploitation instead. Ask where the context comes from and how current it is.
- Measure accuracy on your own assets. Run a proof of value against real systems, not a demo environment. Ask for the request, the response, and the steps to reproduce behind each finding, and track how many results your team has to discard as false positives.
- Match the cadence to your rate of change. If new applications, APIs, and cloud services appear every week, an annual or quarterly test describes an environment that no longer exists. Ask how often each asset is retested and what triggers a new test when something changes.
- Look for control, not just autonomy. Autonomous testing is how AI pentesting reaches scale, but security teams need to see what an agent is allowed to do, review a log of every action, and stop a test at any time. Treat those controls as requirements, not features.
- Keep human penetration testers where they add the most. Experienced testers remain valuable for complex business logic and for engagements that require a signed attestation. Pairing continuous AI pentesting across the surface with focused human testing on the most critical systems gets the most from both.